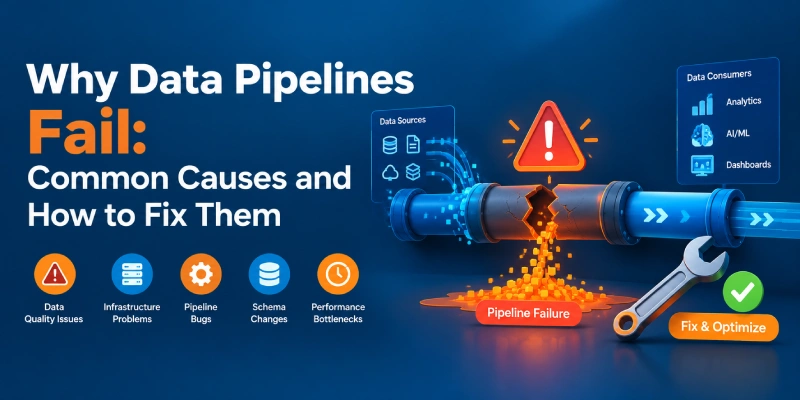
Why Data Pipelines Fail: Common Causes and How to Fix Them
A sales dashboard shows yesterday’s numbers. A forecasting model receives incomplete records. A finance report contains duplicate transactions, even though the overnight data job completed successfully.
Understanding why data pipelines fail requires looking beyond error messages. Some failures stop data processing immediately. Others allow incorrect, incomplete, or outdated information to reach the people and applications that depend on it.
Data pipelines fail when source changes, poor data quality, unreliable connections, capacity limits, unready dependencies, unsafe retries, or weak monitoring disrupt how data moves and is transformed. Preventing recurring failures requires attention to both technical execution and the reliability of the final output.
This guide explains the common causes, how to investigate them, and what businesses can do to build more dependable data workflows.
What Is a Data Pipeline Failure
A data pipeline collects information from source systems, processes it, and delivers it to a destination such as a data warehouse, reporting platform, or machine learning application. A failure occurs when that workflow misses any of its core requirements:
Delivery
Did the required data reach its destination completely, or were extract batches truncated silently midway?
Accuracy
Is the output complete, valid, and correct, or did unvalidated types or mixed currencies distort numbers?
Timeliness
Did it arrive when the business needed it, or did delayed upstream loads publish stale data into dashboards?
A pipeline can meet one requirement while missing another. For example, a job may load records successfully but omit an entire region’s transactions.
Core Takeaway: A green checkbox in your job orchestrator merely confirms process termination without an uncaught exception — it does not verify that business data arrived intact.
Why Data Pipelines Fail
Data pipelines rarely fail from a single catastrophic outage. Most often, failures stem from subtle source drift, capacity boundaries, unready dependencies, or poorly engineered retry loops. Here are the 7 core breakdown points and how to protect against them.
Source Data Structures Change Unexpectedly
Pipelines depend on assumptions about incoming data: column names, field types, required values, and nested structures.
When an upstream source application changes those structures without notice, downstream processing breaks. This breakdown is known as schema drift.
Define clear schemas (data contracts) for essential datasets and validate incoming records automatically. Coordinate breaking changes directly with source owners and test transformations before deployment.
- Controlled Catalog Updates: In AWS Glue, configure crawler policies to prevent automatic, unvetted alterations to production schemas.
- Quarantine Routing: Divert non-conforming payloads to a dead-letter queue (DLQ) rather than halting the entire ingestion batch.
Poor Data Quality Reaches Downstream Systems
A pipeline can process technically valid records that are completely unsuitable for business consumption.
Missing customer identifiers, duplicate orders, inconsistent currencies, and invalid timestamps distort reporting without raising a syntax or database error.
Embed business-rule validation gates prior to lakehouse publication:
- Referential Integrity: Verify required identifiers, foreign keys, and reference lookups.
- Uniqueness Constraints: Enforce deduplication keys where repeating events are unacceptable.
- Domain Rules: Validate permitted numerical bounds, date ranges, and category enums.
- Source Reconciliation: Reconcile stage-by-stage row counts and aggregate values against source systems.
APIs and External Connections Become Unreliable
Modern pipelines rely heavily on third-party SaaS APIs, remote microservices, and external cloud storage.
These dependencies suffer from network timeouts, provider rate limits, authentication expirations, or altered pagination semantics that truncate extracts.
Record extraction checkpoints, verify pagination signatures, and distinguish transient network hiccups from persistent configuration errors.
- Bounded Jittered Backoff: Use exponential backoff retries with randomized jitter to respect server rate quotas.
- Token Rotation Alerts: Avoid blind retry loops on HTTP 401/403 auth errors; trigger immediate credential alerts.
Data Volume Exceeds Processing Capacity
A workflow that functions smoothly during testing often degrades or crashes when production data scales up.
Large cross-joins, partition skew, memory limits, and millions of uncompacted micro-files trigger out-of-memory (OOM) errors and balloon compute costs.
Measure performance at individual processing stages. Inspect query execution plans, partition balance, and data skew before increasing cluster size.
- Incremental Processing: Leverage CDC (Change Data Capture) and Delta/Iceberg tables to process only changed delta rows.
- Peak Capacity Modeling: Architect for seasonal spikes and historical backfills rather than average daily volumes.
Tasks Run Before Their Dependencies Are Ready
Pipelines contain interdependent tasks that must run in an exact logical sequence.
If downstream aggregation begins before upstream extracts finish loading, it processes partial data. Scheduling tasks based purely on clock times (e.g., “Task B at 6:00 a.m.”) leads to silent failure.
Define explicit DAG dependencies, event triggers, and readiness conditions rather than arbitrary cron timers.
- Readiness Sensors: Downstream jobs should trigger only upon receiving validated completion signals for the batch interval.
- Late-Arriving Data Logic: Establish documented protocols to automatically reprocess delayed data and update published aggregates.
Retries Create Duplicates or Partial Output
Automated retries recover from temporary blips, but unprincipled retries corrupt data worse than the original failure.
If a batch writes 40,000 records, loses connection, and re-executes with basic INSERT
statements, records get duplicated.
Design every operation to be idempotent: executing a job multiple times with identical inputs must always yield the exact same outcome.
- Upserts & Atomic Writes: Use
MERGE INTOlogic, transactional lakehouse tables, or deterministic partition replacements. - Airflow Best Practices: Adhere to Apache Airflow guidelines by scoping retries to specific input partitions and testing failure modes during write phases.
Monitoring Misses Problems and Ownership Is Unclear
Some data pipelines remain perpetually fragile because teams cannot quickly discern what went wrong or who is responsible for the resolution.
Engineers often suffer alert fatigue from unhelpful messages like “Job failed: exit code 137,” which lack data context, affected records, or business blast radius. Meanwhile, a pipeline that finishes “successfully” while writing stale or empty tables triggers zero alerts at all.
Pair process execution metrics with rigorous checks on the actual data payload:
- Data-Level Telemetry: Monitor freshness, completeness, null ratios, and distribution anomalies against business-defined SLAs.
- Automated Freshness Checks: Leverage tools
like dbt to enforce source freshness thresholds (
dbt source freshness) before triggering downstream transformations. - Clear Accountability & Runbooks: Assign an unambiguous owner and escalation path for every production pipeline. Whether governance is centralized or domain-oriented depends on your architectural model — our comparison of data fabric vs. data mesh architecture explains how each framework manages pipeline ownership.
Why Data Pipelines Fail at a Glance
A concise field guide summarizing failure patterns, production symptoms, and primary remediation moves.
| Cause & Area | Production Symptom & Blast Radius | Engineering First Move |
|---|---|---|
| Source schema drift | Renamed or new fields break transformations; nulls or coercion errors corrupt tables. | Enforce data contracts, isolate unvetted schema updates, and test transformations before release. |
| Poor data quality | Duplicates, mixed currencies, and orphaned foreign keys distort executive analytics. | Implement business-rule validation gates and stage-by-stage reconciliation against source totals. |
| Unreliable connections | Timeouts, rate-limit throttling, expired tokens, or truncated multi-page extracts. | Apply bounded retries with jitter; track extraction cursors; rotate credentials on auth failures. |
| Volume beyond capacity | Worker out-of-memory crashes, partition skew bottlenecks, and small-file latency. | Analyze query plans, balance partition keys, adopt incremental processing, and plan for peak spikes. |
| Unready dependencies | Downstream jobs run on partial loads and publish half-baked metrics to dashboards. | Replace static clock timers with DAG sensors, readiness signals, and late-arriving data protocols. |
| Unsafe retry loops | Duplicated records or fragmented batch writes generated upon job re-execution. |
Ensure idempotent writes: employ upserts (MERGE),
transactional tables, or partition replacement.
|
| Weak monitoring & ownership | Low-signal alert spam; stale data published with zero warning; ambiguous ownership. | Pair payload checks (freshness, completeness) with execution logs; designate domain owners. |
How to Diagnose a Failed Data Pipeline
Effective troubleshooting starts with the affected business output and works backward upstream to the earliest point of divergence.
1. Define the Business Impact
Identify which reports, applications, customer experiences, or executive decisions depend on the affected dataset. Establish whether the issue involves missing records, distorted calculations, late arrival, or total system unavailability.
Scoping the business blast radius determines triage urgency and informs whether downstream data publication should immediately pause to prevent decision contamination.
2. Locate the First Incorrect Stage
Compare the source extract, raw landing bucket, intermediate transformations, and final analytical mart.
Pinpoint the earliest transformation where record volumes, null ratios, or values deviate from expectations. A calculation error visible in the reporting BI layer frequently originates multiple hops earlier during ingestion.
3. Compare With the Last Healthy Run
Review changes in pipeline code, configuration files, permission grants, source schemas, and data distribution.
Ensure comparisons evaluate the identical processing interval — contrasting mismatched calendar windows can obscure root causes. Forward-looking teams now integrate AI agents in data engineering to aggregate run histories, schema diffs, and error logs into a consolidated triage summary, though engineering oversight remains essential.
4. Recover and Validate Output
Remediate the underlying bug before re-executing affected data workflows. Constrain reprocessing strictly to the impacted partitions or temporal intervals to prevent unnecessary compute spend.
Following recovery, reconcile row counts and aggregates against source systems and confirm downstream reports. A completed rerun alone does not guarantee operational health until verified.
An Example of a Successful Job With Incorrect Revenue
A detailed walkthrough showing how a silent failure bypassed operational monitoring at a high-volume retailer.
The Scenario
A multi-channel retailer ingests online orders into an enterprise reporting warehouse every night to populate executive revenue dashboards.
The Silent Failure
The nightly ingestion job completes without error, but the morning revenue figure drops 22%. Investigation
reveals that the e-commerce team introduced a new order status
(“AUTHORIZED_PENDING_FULFILLMENT”). The existing transformation filter explicitly
listed only previous status strings, silently discarding valid revenue.
Why It Mattered
Nothing crashed. The system logged zero errors. The breakdown occurred purely because business logic drifted from the upstream source application.
The Fix Path
The immediate fix was updating the filter and reprocessing the batch. The durable engineering improvement was adding an unknown-status anomaly alert and source revenue reconciliation checks to detect unmapped values automatically.
How to Improve Data Pipeline Reliability Over Time
Resilient pipelines require repeatable engineering standards, robust automated testing, and clear operational practices.
-
1. Prioritize High-Impact Datasets
Begin with the core datasets driving revenue, compliance, and customer decisions. Establish explicit thresholds for freshness, completeness, and reconciliation tolerances for each one.
-
2. Test Edge Cases & Version Configurations
Test transformations using realistic scenarios: empty inputs, unexpected schemas, duplicated timestamps, and out-of-order batches. Maintain all pipeline code, dbt models, and orchestrator configs under strict version control.
-
3. Preserve Source History for Recovery
Retain raw source history in an immutable bronze/landing zone for an appropriate duration, balancing regulatory retention requirements with disaster replay capabilities.
-
4. Document Idempotent Replay Runbooks
Standardize runbooks detailing how on-call engineers can replay a compromised batch without accidentally duplicating transactions or overwriting adjacent partitions.
-
5. Conduct Incident Post-Mortems
Review recurring failures systematically. If engineers repeatedly resolve the same incident through manual intervention, address the underlying architecture or ownership flaw.
The Golden Rule of Data Ops: Investing in additional tooling can assist, but software tools cannot substitute for clear data contracts, tested recovery procedures, and accountable domain teams.
Build Data Pipelines Your Business Can Depend On
Understanding why data pipelines fail empowers engineering teams to transition from reactive midnight incident firefighting to dependable, automated data delivery.
The priority is making failures immediately visible, isolating non-conforming data, and recovering safely without downstream disruption. That requires coordinated architecture across ingestion, transformation, validation, and domain governance.
Talent Smart partners with modern enterprises to design, optimize, and manage resilient data workflows. Explore our data engineering services to learn how we help collect, validate, and prepare reliable data for analytics and AI initiatives.