How to Build a Production-Ready RAG Application
A practical framework for turning a Retrieval-Augmented Generation prototype into a system that holds up under real production traffic.
A working demo and a system that survives real users are two different products.
Retrieval-Augmented Generation looks deceptively simple once the first prototype answers a question correctly — plug an embedding model into a vector store, wrap it with an LLM call, and the magic seems to work. Then real traffic arrives: documents change daily, questions get messier, and the same pipeline that impressed a demo audience starts returning confident, well-written, wrong answers.
Building a production-ready RAG application is not about assembling more components. It is about designing each stage of the pipeline — ingestion, retrieval, generation, and evaluation — so it holds up under scale, ambiguity, and constant data drift. This guide walks through the framework that separates a RAG prototype from a system teams can depend on.
What Production-Ready Actually Requires
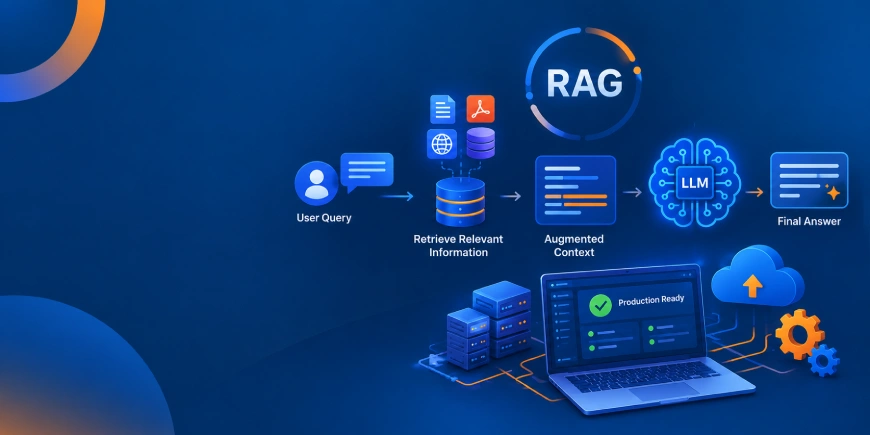
Retrieval-Augmented Generation pairs a search step with a generation step: relevant passages are retrieved from a knowledge base and passed to an LLM as grounding context, so it answers from real, current data instead of only what it memorized in training. Understanding how LLMs process and generate language provides useful context for evaluating how RAG supplies those models with external, up-to-date information. That core loop is well understood.
Scalable Retrieval
Retrieval that stays accurate as the corpus grows into the millions.
Meaning-Preserving Chunks
A chunking strategy that preserves meaning instead of slicing sentences in half.
Grounded Answers
A way to measure whether answers are actually grounded, not just fluent.
Drift-Aware Monitoring
Monitoring that catches silent quality drops before users do.
Cost, Latency & Access Guardrails
Guardrails around cost, latency, and data access.
None of this shows up in a weekend demo. All of it shows up in week three of production traffic.
Why Most RAG Prototypes Break in Production
A handful of failure patterns show up repeatedly across RAG deployments:
-
Naive chunking
Fixed-size blocks ignore structure and often cut a key fact in half, so neither resulting chunk retrieves cleanly.
-
Vector-only search
Semantic search misses exact matches like product codes or clause numbers that keyword search would catch instantly.
-
No evaluation loop
A pipeline ships, works in a demo, and there's no repeatable way to tell if the next change made retrieval better or worse.
-
Stale indexes
Source documents update but the vector index doesn't, so the system confidently cites a policy that no longer applies.
-
Unbounded context stuffing
Retrieving more chunks “to be safe” inflates cost and latency while handing the model conflicting or irrelevant context.
Fixing these after launch is expensive. Designing around them from day one is not.
A Practical Framework for Production RAG
Structure Ingestion Around Meaning, Not File Size
Ingestion & chunkingChunking is the single most underrated decision in a RAG pipeline. Fixed-size splitting is the default in most tutorials, and it's the wrong default for real workloads because it ignores paragraph, section, and table boundaries. Semantic or structure-aware chunking — grouping text by topic coherence rather than token count — consistently produces cleaner, more retrievable passages. A practical starting point is 256–512 tokens per chunk with 10–20% overlap, adjusted by document type: contracts and manuals often need larger chunks; FAQs and tickets do well with smaller, self-contained ones.
Attach metadata to every chunk — source, section, last-updated date, document type. Metadata filtering later is one of the cheapest ways to improve precision.
Choose Infrastructure for Where You're Headed
Vector store & reindexingThe right vector database depends on scale and existing infrastructure, not hype. Under roughly one million vectors on an existing PostgreSQL stack, pgvector avoids new infrastructure. Early-stage or prototyping workloads move faster on Qdrant or Chroma. Large-scale production with managed operations typically calls for Pinecone or Weaviate to reduce the operational burden.
Vector database selection at a glance
| Vector database | Best suited for | Scale sweet spot | Why teams choose it |
|---|---|---|---|
| pgvector | Teams already running PostgreSQL | Under ~1 million vectors | Avoids standing up new infrastructure |
| Qdrant / Chroma | Early-stage builds & prototyping | Fast-iteration workloads | Quick to stand up, flexible to change |
| Pinecone / Weaviate | Large-scale production | Millions of vectors | Managed operations reduce the ops burden |
Whatever the choice, plan for reindexing from the start — embedding models improve and document sets change shape, so a pipeline that can only build an index once will need painful rework later.
Combine Semantic and Keyword Search
Hybrid retrieval + rerankingPure vector search misses exact-match terms — an ISO clause number, a SKU, a legal citation — because semantic similarity doesn't guarantee lexical overlap. Pure keyword search (BM25) misses paraphrased or conceptually related queries. Hybrid retrieval, which blends both and re-ranks the combined results, is consistently the highest-leverage upgrade a team can make to a naive RAG pipeline. Adding a reranking step on top — scoring the top candidates with a cross-encoder before they reach the LLM — further improves precision on ambiguous or multi-part questions.
Assemble Context Deliberately
Precision over volumeMore retrieved chunks is not automatically better. Passing ten loosely relevant passages to the model increases cost and latency, and raises the odds it has to reconcile conflicting information. A tighter context window with three to five well-ranked chunks usually outperforms a wider, noisier one. Where possible, separate the chunks used for retrieval scoring from the surrounding context used for synthesis, so the model has enough to answer fully without retrieval precision getting diluted by oversized chunks.
Build an Evaluation Loop Before You Need One
Golden datasets & scoringWithout measurement, every pipeline change is a guess. A practical evaluation setup includes a golden dataset of 50–100 representative question-answer pairs covering real use cases, automated scoring on faithfulness, relevance, and context precision, and evaluation runs after every meaningful pipeline change — not just before major releases.
If faithfulness scores drop, the fix is almost always in retrieval, not generation. Hallucination in RAG is more often a symptom of the wrong context than the model inventing facts.
Instrument Observability From Day One
Latency, drift & logsProduction RAG needs visibility into more than uptime. Track retrieval latency separately from generation latency, log which chunks were retrieved for each query, and watch for silent drift — retrieval quality degrading gradually as the corpus grows. Time-to-first-token and end-to-end response time both deserve explicit budgets, since users judge a RAG assistant on responsiveness as much as accuracy.
Much of this observability discipline mirrors broader scalability practices that apply beyond RAG — the same monitoring, caching, and resilience patterns that keep any production system healthy under real load, from database-heavy applications to distributed microservices.
Treat Security as Architecture, Not an Afterthought
Access control & audit trailsOnce a RAG application touches real business data, access control has to be enforced at the retrieval layer, not just the application layer — a user should never retrieve chunks from documents they aren't authorized to see. For regulated industries, an audit trail of which index version and which retrieved chunks produced each answer is increasingly a baseline requirement, not a nice-to-have. Building this in from the start is far cheaper than retrofitting it after an audit finding.
Metrics That Actually Define Production Readiness
A RAG application is production-ready when it can be measured, not just demoed. The metrics that matter most:
| Metric | What it actually tells you |
|---|---|
| Faithfulness | Does the answer stay grounded in retrieved context |
| Context precision & recall | Are the right chunks retrieved, and is the corpus covered |
| Latency (p90/p95) | Response time under realistic, not best-case, load |
| Cost per query | Token usage across retrieval and generation combined |
| Index freshness | The gap between a source document changing and the index reflecting it |
Teams that track these from the first deployment catch regressions in days instead of discovering them through user complaints months later.
Bringing It Together
A production-ready RAG application is the result of disciplined engineering across ingestion, retrieval, generation, and evaluation — not a bigger model or a fancier prompt. Teams that treat chunking, hybrid search, evaluation, and observability as core architecture decisions from day one ship systems that hold up under real usage; teams that treat them as later optimizations spend months firefighting instead. The gap between a RAG demo and a RAG product is almost entirely made up of these decisions.
Organizations building AI-powered applications on their own data increasingly need this expertise in-house or through an experienced partner. Explore TalentSmart's AI and software development services to design and deploy a retrieval architecture built for real production traffic.
Frequently Asked Questions
What is the difference between RAG and fine-tuning?
Fine-tuning changes how a model behaves — tone, format, domain vocabulary — by retraining it on examples. RAG changes what a model knows by retrieving current, external information at query time. Most production systems use both: fine-tuning for behavior, RAG for real-time grounding.
How much data is needed to build a RAG application?
There's no fixed minimum. RAG works with a few hundred documents or several million; document quality, structure, and a chunking strategy that fits the content type matter more than raw volume.
Why does my RAG application hallucinate even with retrieval in place?
Usually the model isn't inventing facts — it's being handed the wrong context. Poor chunking, weak retrieval ranking, or an overly broad context window are the most common root causes and should be ruled out before blaming the model.
Which vector database should I use?
It depends on scale and infrastructure. Teams on PostgreSQL with a modest corpus often start with pgvector; teams needing managed scaling at millions of vectors typically move to Pinecone, Weaviate, or Qdrant.
How do I know if my RAG system is ready for production?
It should have a documented evaluation baseline, hybrid retrieval with reranking, monitored latency budgets, and access controls enforced at the retrieval layer — not just a pipeline that looks reasonable in testing.
Ready to move your AI initiatives from prototype to production?
Talk through your next build with a team that has done this before.
Get in touch with TalentSmart